Softude
For most enterprise LLM applications, RAG is the better starting point when the model needs current, proprietary information. Fine-tuning is worth considering when the model consistently underperforms on a specific task despite appropriate prompting. Use both when an application needs current knowledge and specialized behavior, but validate the additional complexity through testing.
Key highlights
- RAG supplies external knowledge at inference time; fine-tuning adapts a model’s behavior.
- Choose RAG for frequently changing information and source traceability.
- Consider fine-tuning for specialized classification, extraction, or consistent output formats.
- A hybrid approach makes sense when an application needs both capabilities.
- Compare accuracy, security, latency, and total cost before selecting an architecture.
Why Should Enterprises Compare RAG And Fine-Tuning?
Enterprises must compare RAG and fine-tuning because both fix a different gap. RAG addresses missing or changing knowledge, making it essential for building smart chatbots, while fine-tuning addresses inconsistent model behavior. Choosing the wrong technique can increase your model cost and delay rollout. Even then, the final AI solution will still miss the business requirement.
A foundation model on its own does not know a company’s internal policies, product details, or customer records, and it may not produce outputs in the format a business process requires. The decision to choose between RAG and fine-tuning should depend on four factors :
- Access to proprietary and current information
- Consistent outputs and task performance
- Data access controls and auditability.
- Predictable operating cost and effort.
What Is The Difference Between RAG And Fine-Tuning?
RAG connects a large language model (LLM) to an external knowledge source and retrieves relevant information for each query. Fine-tuning trains the model on examples that demonstrate the desired behavior.
How does retrieval-augmented generation (RAG) work?
A RAG pipeline retrieves information from approved sources and provides it as context for the LLM’s response. A typical implementation involves six stages:
- Data ingestion: Collect approved documents, knowledge-base articles, or database records.
- Preprocessing: Clean the data and divide documents into meaningful sections.
- Indexing: Create searchable representations of the content.
- Retrieval: Find relevant passages using semantic search, keyword search, or both.
- Context construction: Select and organize evidence for the model.
- Generation: Use the retrieved evidence to answer the user’s question.
RAG does not guarantee correct answers. Document quality, retrieval relevance, access permissions, and the model’s interpretation of evidence all affect the result. Teams must evaluate the full pipeline, not just the language model.
What does fine-tuning do?
Fine-tuning continues training a pretrained model on a curated dataset to improve its performance on a defined task. Depending on the training objective and examples, it can help with:
- Classification and structured information extraction
- Consistent output formats and terminology
- Specialized instruction following
- Repeated task-specific response patterns
Fine-tuning changes learned behavior; it does not create a dependable, live knowledge source. It also requires representative training data and testing on unseen examples to establish whether performance has improved without introducing regressions.
RAG Vs Fine-tuning Full Comparison
| Comparison factor | RAG | Fine-tuning |
| Primary purpose | Supply relevant external knowledge | Adapt model behaviour |
| Knowledge updates | Refresh approved sources and indexes | May require additional training |
| Task consistency | Can improve through context and instructions | Can improve through representative examples |
| Source references | Can provide citations to retrieved evidence | Does not inherently provide citations |
| Access control | Can enforce permissions during retrieval | Does not inherently enforce user-level permissions |
| Hallucination management | Can ground answers in retrieved evidence | Does not inherently ground answers |
| Cost drivers | Data processing, indexing, retrieval, context tokens | Data preparation, training, evaluation, hosting |
| Maintenance | Data pipelines, indexes, retrieval quality | Training data, model versions, regression testing |
| Typical fit | Knowledge-intensive applications | Specialised, behaviour-intensive tasks |
These are typical differences, not guaranteed outcomes. The model, implementation, workload, and evaluation criteria determine actual performance.
Which Is Better For Enterprise LLMs: RAG Or Fine-Tuning?
RAG is usually the stronger starting point for knowledge-intensive enterprise applications. According to Menlo Ventures’ report 34% of enterprise production deployments use RAG (vector search), compared with 12% using fine-tuning. Fine-tuning becomes relevant when testing reveals a persistent gap in task performance.
What Factors Matter Most When Comparing RAG And Fine-Tuning?
The most important factors are knowledge freshness, task performance, security, accuracy, latency, total cost, and ongoing maintenance.
Why is knowledge freshness important for enterprise LLMs?
RAG is better suited to applications that depend on frequently changing information because teams can update approved sources and refresh the retrieval index without retraining the model. Fine-tuning is less suitable as the primary way to maintain current business facts because its model weights are not a live, searchable knowledge base.
For example, a conversational AI assistant answering questions about employee policies, product specifications, inventory, or compliance procedures needs access to the latest approved information.
Decision rule: Start with RAG when information changes frequently, or answers must be traceable to approved sources. Consider fine-tuning separately if the application also needs specialized task behavior.
How do task performance and model behavior affect the choice?
Fine-tuning is worth testing when a model has the necessary information but repeatedly struggles with a defined task, such as extracting contract fields, classifying records, or following a required output schema.
Before training, check whether clearer instructions, a better base model, output validation, or improved retrieval can solve the problem. Fine-tuning adds value only if it improves results beyond those simpler alternatives.
Decision rule: Consider fine-tuning if performance gaps in the AI model persist after appropriate prompting and configuration. Use RAG when the main problem is missing or inaccessible information.
How do RAG and fine-tuning compare on security and governance?
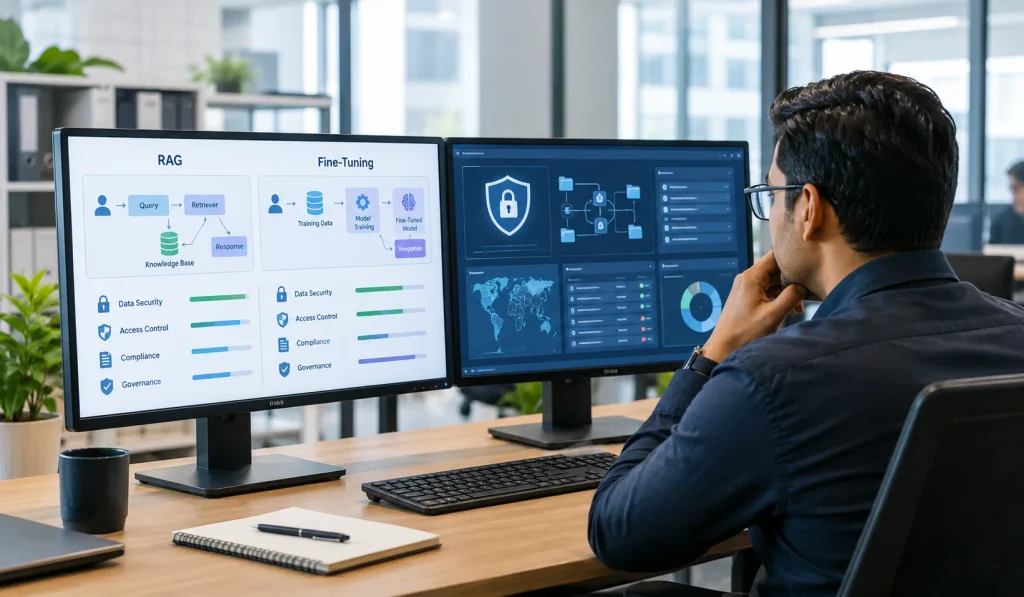
Neither approach is inherently secure or compliant. RAG can enforce document-level permissions at retrieval time and provide source metadata for auditing. Fine-tuning requires controls over training data, model artifacts, and the information exposed during training.
An enterprise must assess the complete system against the organization’s threat model and compliance requirements. Do not treat either architecture as a substitute for security controls.
- User permissions, tenant isolation, and access enforcement
- Data retention, deletion, and sensitive information handling
- Prompt injection in user inputs and retrieved documents
- Audit trails, human approval, and escalation procedures
Softude helps enterprises choose the right architecture for LLM Development. Our team begins with a validation approach that includes checking data quality, testing edge cases against real business scenarios, running pilots, and monitoring performance after deployment. These checks help determine whether a proposed architecture meets production requirements rather than simply performing well in a demo.
RAG or Fine-tuning: which approach improves accuracy and reduces hallucinations?
Neither RAG nor fine-tuning guarantees correctness. RAG can ground responses in retrieved evidence, while fine-tuning can improve performance on specific tasks. Both need AI evaluation against realistic inputs.
For RAG, test cases where evidence is relevant, missing, outdated, or contradictory. For fine-tuning, evaluate unseen examples and edge cases to check whether the model generalizes rather than memorizes training data.
Measure retrieval quality, answer correctness, groundedness, task success, and appropriate abstention separately.
How do latency and scalability compare?
RAG adds retrieval and context-processing steps, potentially including search, reranking, and permission checks. Fine-tuning does not automatically make inference faster, although a specialized smaller model may be efficient for a narrow task.
Compare end-to-end latency, throughput, concurrency, failure rates, and context size under realistic workloads. A system that performs well in a small test may behave differently under production traffic.
Decision rule: Choose the architecture that meets your response-time and throughput requirements while maintaining the necessary task quality.
What do RAG and fine-tuning cost?
RAG costs typically include data processing, indexing, search infrastructure, context tokens, and ongoing retrieval maintenance. Fine-tuning costs include data preparation, training, evaluation, model hosting, deployment, and potential retraining.
Compare total cost of ownership and cost per successful task, not just the cost of an individual model call. Include human review, failed requests, retries, infrastructure, and maintenance. There is no universal query-volume threshold at which fine-tuning becomes cheaper than RAG; the answer depends on model pricing, task quality, context size, and deployment requirements.
Decision rule: Benchmark realistic workloads and compare the full operating cost of building AI against the existing process.
Consult Softude’s LLM experts if you need help with LLM cost estimation for each task.
Which approach is easier to maintain?
RAG requires teams to maintain source data, document processing, indexes, retrieval settings, and permissions. Fine-tuning requires versioned training datasets, model management, regression testing, and controlled deployment.
Both need repeatable evaluations, monitoring, and rollback procedures. A hybrid system adds the operational demands of both approaches, so its benefits should justify the extra complexity.
When Should Enterprises Use RAG Technique?
RAG is a strong fit when answers depend on current company knowledge or need evidence from approved sources.
- Enterprise knowledge assistants: Retrieve internal policies, technical documentation, and product information.
- Customer support: Ground responses in current troubleshooting guides and approved policies.
- Document search and compliance: Find relevant passages across large document collections and provide references for human review.
These applications depend on source quality and retrieval performance. Complex legal, financial, or compliance decisions may also require deterministic checks and human oversight.
When Should Enterprises Use Fine-Tuning?
Fine-tuning is most relevant to repeated tasks with clear expected outputs and enough representative examples to train and evaluate the model.
- Structured extraction and classification: Improve consistency when identifying fields or assigning categories.
- Specialized terminology and output formats: Reinforce domain-specific conventions that instructions alone do not reliably produce.
- Narrow, high-volume workflows: Evaluate whether a specialized model can meet quality requirements at a lower operating cost.
High volume alone is not a reason to fine-tune. Compare performance, latency, hosting, and maintenance against the existing model and other simpler alternatives.
Should Enterprise Use Both RAG And Fine-Tuning for LLMs?
Yes. A hybrid architecture is the best approach to keep your LLMs’ knowledge updated while improving it for specialized tasks.
For example, a contract-processing system could retrieve the latest approved contract clauses through RAG and use a fine-tuned model to extract renewal dates and specified fields consistently.
A hybrid approach is worth testing when retrieval provides the right evidence but task execution remains unreliable, or when fine-tuning improves behavior, but the application still needs current external information.
To establish whether the added complexity is justified, compare four configurations on the same representative test set:
- A foundation model with appropriate prompting
- RAG with the foundation model
- A fine-tuned model without retrieval
- A fine-tuned model with RAG
Measure task quality, groundedness, latency, cost, and reliability. Retain the hybrid design only if its measured benefits justify the additional infrastructure and maintenance.
Choosing The Right Enterprise LLM Architecture
RAG supplies knowledge, fine-tuning shapes behavior, and agents turn both into action, which makes the right choice a matter of diagnosing the gap in front of you. Starting with the simplest architecture that passes representative tests keeps cost per successful task, security exposure, and maintenance effort in check as the system scales.
To understand how to benchmark RAG, fine-tuning, and agentic options on your own workloads, consult Softude’s AI experts.
FAQs
Is RAG cheaper than fine-tuning for enterprise LLMs?
It depends on the workload. RAG incurs retrieval, indexing, and context-processing costs, while fine-tuning incurs data preparation, training, evaluation, and model-management costs. Compare total cost of ownership and cost per successful task.
Can fine-tuning teach an LLM new company knowledge?
Fine-tuning can influence what a model reproduces, but it is not a dependable way to maintain changing business facts or provide source citations. RAG is generally a better starting point when information must stay current and traceable.
Does RAG eliminate hallucinations?
No. RAG can ground responses in retrieved evidence, but retrieval may miss relevant information, return outdated content, or the model may misinterpret it. Evaluate retrieval quality and answer correctness separately.
Should enterprise fine-tune a model to build an AI agent?
No. Many agents can start with a capable foundation model, appropriate prompts, RAG, and tools. Consider fine-tuning only when testing identifies a persistent performance gap, and the chosen provider supports the required training method.
How is RAG different from agentic AI?
RAG retrieves relevant information and generates an answer. Agentic AI uses an LLM to plan steps, call tools, and act toward a goal. Agentic RAG combines retrieval with an agent that can decide what to retrieve and whether more information is needed.